Frame bounded NDJSON records across byte chunks
AI assisted the preparation of this article, and its Python example was tested locally with synthetic fixtures.
A byte chunk is not necessarily a complete NDJSON record. It can end inside a JSON value, between a carriage return and newline, or in the middle of a UTF-8 character. Buffer bytes until a line terminator arrives, and bound each raw line before decoding it.
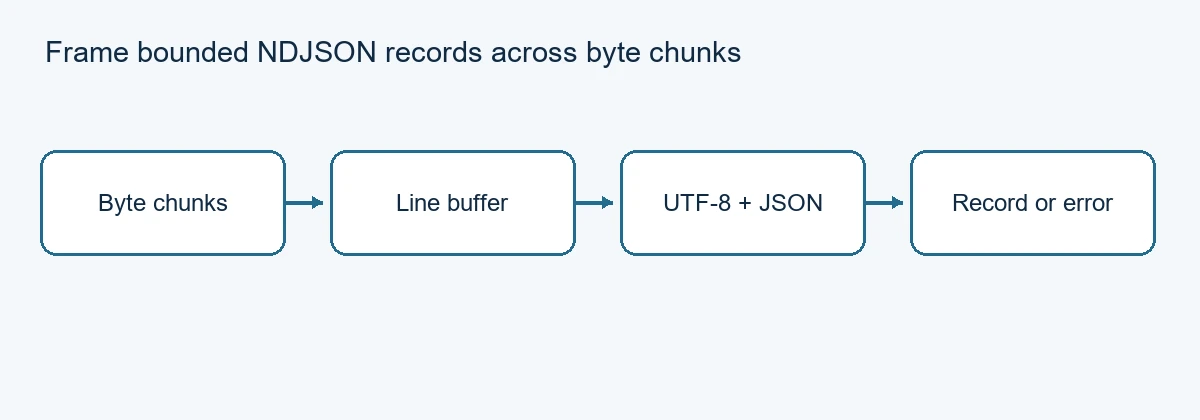
Flow: Byte chunks, then Line buffer, then UTF-8 + JSON, then Record or error.
Define the line contract
This small fixture accepts LF and CRLF, rejects empty lines and requires the final record to end with a newline. The byte limit includes the LF and any preceding CR. An entirely empty stream returns an empty list. Every input chunk must be bytes.
import json
import math

def parse_records(chunks, max_line):
    if type(max_line) is not int or max_line < 1:
        raise ValueError("invalid line limit")
    def reject_constant(value):
        raise ValueError("non-finite constant")
    def finite_float(value):
        number = float(value)
        if not math.isfinite(number):
            raise ValueError("number outside float range")
        return number
    buffer = b""
    records = []
    for chunk in chunks:
        if not isinstance(chunk, bytes):
            raise ValueError("chunks must be bytes")
        buffer += chunk
        while b"\n" in buffer:
            index = buffer.index(b"\n")
            line, buffer = buffer[:index + 1], buffer[index + 1:]
            if len(line) > max_line:
                raise ValueError("line too long")
            text = line[:-1]
            if text.endswith(b"\r"):
                text = text[:-1]
            if not text:
                raise ValueError("empty line")
            if b"\r" in text:
                raise ValueError("unexpected carriage return")
            try:
                records.append(json.loads(text.decode("utf-8"),
                    parse_constant=reject_constant, parse_float=finite_float))
            except (UnicodeDecodeError, ValueError):
                raise ValueError("invalid record") from None
        if len(buffer) >= max_line:
            raise ValueError("line too long")
    if buffer:
        raise ValueError("unterminated final line")
    return records
A line of {} followed by LF takes three bytes. The same record with CRLF takes four. Test both at the exact limit and test a split inside a multibyte character. Decoding happens only after the complete line is assembled, so a valid character split across input chunks is not lost.
The parser rejects NaN and Infinity, which Python's JSON parser otherwise accepts as extensions. A syntactically valid number such as 1e999 can overflow Python's float range; the explicit float policy rejects that too. It does not impose a general numeric precision or integer-range policy.
The NDJSON specification at commit 8a5a2350 specifies UTF-8 and LF-delimited JSON and permits CRLF. Its empty-line policy may be configured; this fixture rejects empty lines. Python 3.13 JSON documents its parser behavior and resource warning.
Bound the rest of the pipeline
This function collects all parsed records and appends an entire supplied chunk before checking its lines. The caller must bound individual input chunks, total input, record count and stream duration. Line limits alone do not bound parser CPU, nesting depth, integer size or the memory occupied by the returned list.
A valid parsed object still needs schema, duplicate-key and authorization checks. This fixture does not implement them or claim compatibility with a particular provider's event stream. The tests use synthetic local bytes on CPython 3.13.5.